Claude Code with Ollama vs Claude Code Local: benchmark on small Macs
I ran the same 10 coding tasks through Claude Code on two local servers, Ollama and Claude Code Local, 30 runs per model on each. Reliability came out the same. On Qwen 3.5 2B, Claude Code Local passed 28 of 30 and Ollama 25 of 30, a gap too small to call at this sample size, and on the 4B both passed all 30. The difference is speed: a typical task finished 2.8x faster on the 2B and 1.2x faster on the 4B with Claude Code Local.
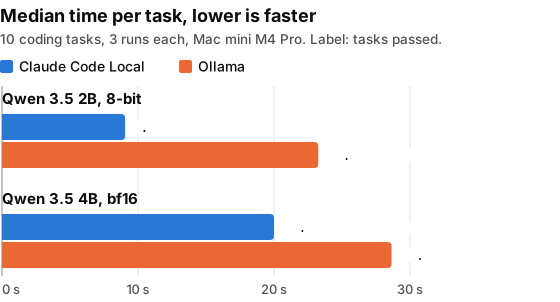
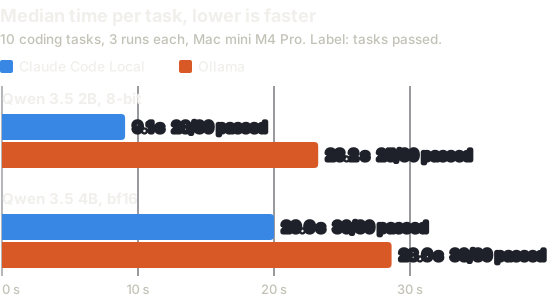
The bars are the median over all 30 runs. The 2.8x and 1.2x are the median of the ten per-task ratios, which keeps one slow task from deciding the result. Measured straight off the bars it is 2.6x and 1.4x.
The results
Qwen 3.5, each server the way its docs set it up
| Model | Server | Tasks passed | Valid tool calls | Median time per task | Time vs Claude Code Local |
|---|---|---|---|---|---|
| Qwen 3.5 2B, 8-bit | Claude Code Local | 28/30 | 165/166 | 9.1 s | 1.00x |
| Qwen 3.5 2B, 8-bit | Ollama | 25/30 | 320/322 | 23.2 s | 2.81x |
| Qwen 3.5 4B, bf16 | Claude Code Local | 30/30 | 100/100 | 20.0 s | 1.00x |
| Qwen 3.5 4B, bf16 | Ollama | 30/30 | 118/118 | 28.6 s | 1.17x |
Most of the time gap is turns, not raw speed. Over its 30 runs the 2B took 352 turns on Ollama and 147 on Claude Code Local. A recurring failure on the 2B is a file path with its leading slash dropped (private/tmp/... for /private/tmp/...). Claude Code Local puts the slash back. On Ollama those paths reached Claude Code in 15 of the 30 runs, and in 3 of Ollama's 5 failures the file landed in the wrong folder.
Gemma 4 E4B, and the bug this benchmark found
The first Gemma run went to Ollama, 27/30 against 20/30, because of a bug in Claude Code Local. With the stock Gemma 4 chat template, every tool result was dropped from the prompt, so the model never saw what its tools returned. In 18 of those 30 runs it said so in its own words. The fix (#89) sends tool calls to templates like this one in the structured form they expect, and leaves every other template exactly as it was. After the fix the two servers tie.
| Gemma 4 E4B, 8-bit | Tasks passed | Valid tool calls | Median time per task |
|---|---|---|---|
| Claude Code Local, before #89 | 20/30 | 142/144 | 19.9 s |
| Claude Code Local, with #89 | 27/30 | 185/185 | 21.4 s |
| Ollama | 27/30 | 77/77 | 20.8 s |
| Ollama, temperature 0.2 | 29/30 | 81/81 | 20.4 s |
I reran Qwen 3.5 2B on the fixed server as a check: 28/30, the same as before.
Where Ollama won
- Raw generation speed on the 4B. Ollama put out 21.0 tokens per second of API time against 17.8 on Claude Code Local. It still finished the tasks later because it took more turns.
- Gemma 4 E4B at temperature 0.2. Ollama with Claude Code Local's sampling setting passed 29 of 30, the best Gemma result in this benchmark. The gap over 27/30 is two runs, so it may be noise, but it is the top number.
- Qwen 3.5 4B at temperature 0.2. Ollama finished level on time with Claude Code Local (0.97x) and passed 29 of 30.
How it was run
- Machine: Mac mini, M4 Pro, 64 GB, macOS 27.2. One server running at a time. The harness refuses to start if the other one is up.
- Client: Claude Code 2.1.306 for every run, as
claude -p <task> --output-format stream-json --verbose --bare --dangerously-skip-permissions --no-session-persistence. Each run got a fresh empty work folder and a fresh Claude Code config, with a 5 minute limit. - Servers: Claude Code Local from this repo (
proxy/server.py) with its small-Mac settings. Ollama 0.35.1 set up the way its Claude Code page says, with a 64K context. - Tasks: 10 small coding jobs that need tools: write a file, edit one value, fix code from a failing test, run a script and record its output, create and run a program, rename a function across two files, edit JSON, search files and count, fix a syntax error, and build a package with a test and run it. Each has an automatic pass or fail check, and each ran 3 times per setup. The tasks were written before the first run and never changed.
- No cloud: every run went through a local proxy that refuses and logs any outside connection, and the Claude Code process's network sockets were checked every 2 seconds. In all 450 runs there were 0 outside connections.
- Order: the Qwen round ran Claude Code Local 2B, Ollama 2B, Ollama 4B, then Claude Code Local 4B. The Gemma round started with Ollama.
| Model | Claude Code Local | Ollama |
|---|---|---|
| Qwen 3.5 2B | mlx-community/Qwen3.5-2B-MLX-8bit at e6ffd00 |
qwen3.5:2b-q8_0, digest 0689d440…b130a |
| Qwen 3.5 4B | mlx-community/Qwen3.5-4B-bf16 at 491fdc7 |
qwen3.5:4b-bf16, digest 530cc2ae…80b5 |
| Gemma 4 E4B | mlx-community/gemma-4-e4b-it-8bit at 4255b21 |
gemma4:e4b-it-q8_0, digest 3721c812…53f3 |
To rerun the Qwen round yourself (with Claude Code, Ollama, the models above and this repo's MLX environment from setup.sh):
The harness, the tasks, every run as one line of JSON and the full write up with all the control runs are in bench/vs-ollama.
What was not equal
Each server ran the way its own docs set it up. That is what someone installing either one gets, but it means a few things differ. I ran extra control runs for the biggest ones.
- Precision. The 4B is bf16 on both. The 2B and Gemma are 8-bit on both, but MLX and Ollama's GGUF use different 8-bit formats, about the same size.
- Context. Claude Code Local's small-Mac setting is 16K and Ollama's docs ask for 64K. Ollama at 16K was still 1.77x slower on the 2B, with the same 25 of 30.
- Sampling. Claude Code sends no temperature. Claude Code Local then uses 0.2 and Ollama uses each model's own defaults. With Ollama at 0.2 the 2B did worse (20 of 30, it got stuck repeating tool calls), the 4B tied on time, and Gemma did best of all.
- System prompt. Claude Code Local swaps Claude Code's long system prompt for a shorter one. Turning that off made it about 1.2x slower and did not change the pass rates.
- Thinking. Both let Qwen think. On Gemma, Claude Code Local skips thinking by default and Ollama keeps it on.
- Background load. The Mac had its usual services running the whole time, the same for both servers.
This page leaves out a memory comparison. The two servers count memory differently, so the numbers I have would not be fair to either one. It also makes no claim about Claude Code Local's tool-call repairs for broken Gemma output (a missing opener, <function=...> calls, tool name case and aliases). In every Gemma run, neither model sent the kind of broken call those repairs exist for, so this benchmark cannot say whether they help. I did not test Gemma 4 31B because it did not fit next to everything else on this Mac.